In the landscape of modern pharmaceutical research, the "folding problem" has long been considered the final frontier. Since the advent of deep-learning tools like AlphaFold, the scientific community has been dazzled by the ability to predict the three-dimensional architecture of nearly every known protein. Yet, as the industry has pivoted toward applying these models to drug design, a harsh reality has emerged: structure is not always the key to a cure.
Seattle-based biotechnology firm Talus Bio is now challenging the hegemony of structural biology. By introducing its new AI model, Ptarmigan-1, the company is bypassing the traditional, computationally expensive, and often inaccurate process of protein folding entirely. In doing so, Talus Bio claims to have achieved a 5,000-fold increase in the speed of virtual drug screening, opening the door to "undruggable" targets that have long stymied traditional medicinal chemistry.
The Structural Bottleneck: Why "Spaghetti" Defies Traditional AI
For years, drug discovery has relied on the "lock and key" paradigm. Scientists seek to identify a stable, rigid pocket on a protein’s surface where a small molecule can bind, effectively turning a disease-causing protein on or off. While this approach has birthed countless life-saving medicines, it is inherently limited by the nature of human biology.
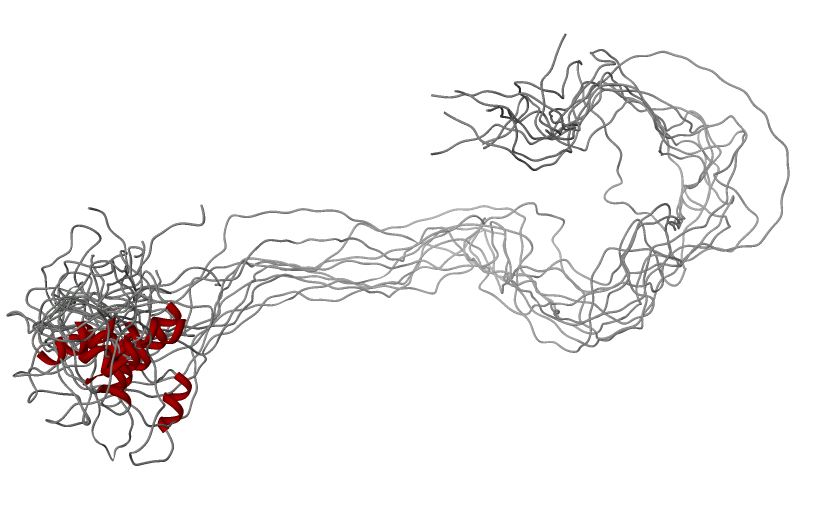
A significant portion of the human proteome—roughly 50%—does not conform to a static, globular structure. These are often categorized as Intrinsically Disordered Proteins (IDPs). A primary example is the family of transcription factors, the "master switches" of the cell that dictate gene expression. When scientists attempt to model these using conventional folding software, the result is what Talus Bio CTO Dr. Lindsay Pino describes as "a plate of spaghetti."
"If you try to fold a transcription factor, you just get a plate of spaghetti," Pino explains. "You can’t do drug discovery on a plate of spaghetti." Because these proteins exist in a state of constant, fluid motion, there is no fixed pocket for a 3-D structure model to identify. Consequently, roughly 87% of the 20,431 human proteins remain without an approved drug or even a known potent small-molecule ligand.
A Chronology of Discovery: From Structural Reliance to Data-Driven Engagement
The journey to Ptarmigan-1 represents a strategic shift in the philosophy of computational biology.
- Pre-2024: The industry was dominated by the emergence of structure-prediction models. While revolutionary, these models required massive computational overhead to predict the 3-D conformation of both the protein and the drug molecule (co-folding).
- Early 2026: Talus Bio began documenting the limitations of structural approaches in their internal research. The team observed that the "snowballing" cost of screening million-compound libraries was becoming a significant barrier to entry, often taking months and costing up to $1 million per target.
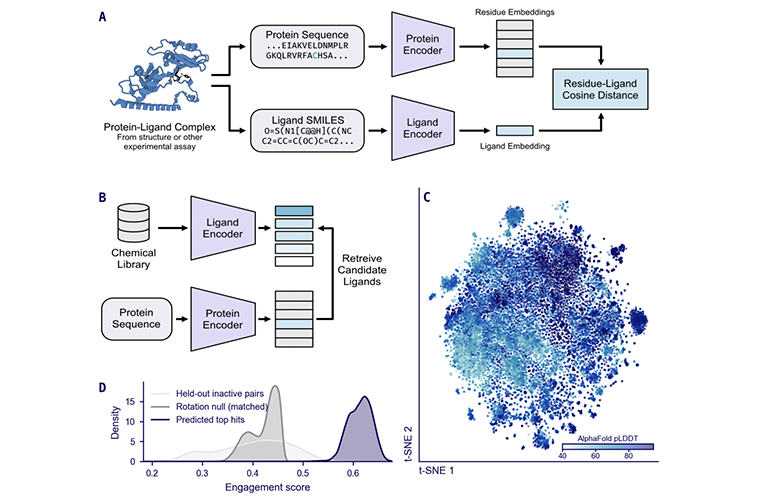
- July 2026: Talus Bio released a groundbreaking preprint detailing the methodology behind Ptarmigan-1. Instead of relying on 3-D structures, the model was trained on high-fidelity mass spectrometry data. This data records in situ target engagement—essentially observing where a compound actually interacts with a protein inside a living cell.
- September 2026: Benchmarking tests confirmed that the model could outperform traditional docking and folding-based methods on complex targets, such as the transcription factor STAT6.
Supporting Data: The Speed and Accuracy of Ptarmigan-1
The metrics reported by Talus Bio are staggering. In a direct head-to-head comparison against Boltz-2—a sophisticated open-source model designed to predict molecular structure and binding affinity—Ptarmigan-1 demonstrated a massive efficiency gap.
The Computational Speed Advantage
When running on a single Nvidia H100 GPU, Ptarmigan-1 averaged approximately 10 milliseconds per compound. In contrast, Boltz-2 required 54 seconds per compound. This 5,000-fold speed advantage is not merely a theoretical curiosity; it changes the economics of the laboratory. A screen of one million compounds that would have previously required nearly two years of continuous computation can now be completed in under three hours.
The Accuracy Benchmark: The Case of STAT6
To validate the model, Talus utilized a retrospective test involving STAT6, a notoriously difficult transcription factor. Using Pfizer patents published after the training cutoff for competitor models, Ptarmigan-1 successfully identified 40 known inhibitors with an Area Under the Curve (AUC) of 0.94. By comparison, both Boltz-2 and standard docking baselines achieved an AUC of 0.58—a score barely better than random chance.
Mass Screening Capability
The scalability of this approach was recently demonstrated in a massive sweep. Talus Bio took a library of 3.4 billion compounds and screened them against the entire human proteome (20,431 proteins). The entire process was completed in less than 24 hours using a modest resource allocation of 20 H100 GPU-hours.
Official Responses: Shifting the Paradigm
The leadership at Talus Bio views Ptarmigan-1 not as an antagonist to structural biology, but as a necessary evolution.
"If you go talk to any scientist or oncologist and ask them what drugs they wish they had, they’re usually for these proteins called transcription factors," says CEO Dr. Alex Federation. The company acknowledges that while structural models excel at well-folded proteins, the future of the field lies in hybrid approaches.
According to the team, the most efficient workflow involves using Ptarmigan-1 as a massive, low-cost filter to narrow down billions of candidates. Once the candidate pool is reduced to a manageable size, structural models can then be used to refine the survivors. This "funnel" approach minimizes wasted computational expense while maximizing the probability of discovering novel binding sites on "undruggable" proteins.
"We’ve been sitting on these targets we’ve known about for decades, that we know are good targets," Dr. Pino adds. "We just haven’t had the tools to find them yet."
The Wider Implications: A New Era for Small-Molecule Design
The success of the Talus Bio approach carries profound implications for the pharmaceutical industry. If structure is no longer the primary requirement for drug discovery, the definition of what constitutes a "druggable" target expands exponentially.
Democratizing Drug Discovery
By significantly lowering the compute cost required to scan massive chemical libraries, Talus Bio is effectively lowering the barrier to entry for early-stage drug discovery. Smaller biotech firms and academic labs, which may not have access to the multi-million-dollar supercomputing budgets required for traditional folding-based screening, could find themselves empowered by "structure-free" AI models.
Addressing Unmet Medical Needs
Transcription factors are frequently implicated in aggressive cancers, autoimmune disorders, and developmental diseases. By effectively "unlocking" these proteins, Talus Bio’s methodology could lead to a new generation of small-molecule therapies for diseases that have remained resistant to conventional medicine for decades.
A Data-First Future
The reliance on mass spectrometry data rather than static crystal structures suggests a shift toward a more empirical, biological approach to AI. By training models on how molecules actually behave in the messy, crowded environment of a living cell, researchers may develop more robust candidates that are less likely to fail in clinical trials due to unforeseen protein interactions.
As the industry continues to digest the findings from the Talus Bio preprint, one thing remains clear: the era of "spaghetti" is ending. By embracing the fluidity of protein biology rather than trying to force it into a static 3-D mold, researchers are moving closer to a future where every human protein is a potential target for therapeutic intervention. The "structure-free" future is no longer a theoretical debate—it is already scanning billions of compounds, one millisecond at a time.
About the Author