The landscape of modern pharmacology was irrevocably altered by the advent of AlphaFold. By solving the "protein folding problem"—a decades-old biological puzzle—Google DeepMind’s flagship software provided the scientific community with a structural atlas of nearly every protein known to science. It was a milestone that earned its creators a Nobel Prize and opened a new frontier in structural biology.
However, as the dust settles on the structural revolution, researchers are confronting a sobering reality: knowing what a protein looks like is not the same as knowing how to drug it. Many of the most elusive biological targets, particularly those involved in aggressive cancers, refuse to sit still for a portrait.
Enter Seattle-based biotechnology startup Talus Bio. The company is currently making waves with the release of "Ptarmigan-1," an AI model that circumvents structural biology entirely. By treating protein-drug interactions as a data-driven mapping exercise rather than a geometry problem, Talus Bio claims to be screening drug candidates 5,000 times faster than current state-of-the-art structural models.
The "Undruggable" Challenge: When Geometry Fails
To understand the significance of Talus Bio’s approach, one must understand the limitation of the status quo. Traditional drug discovery relies on "lock-and-key" dynamics: a small molecule drug fits perfectly into a static, well-defined pocket on the surface of a target protein.
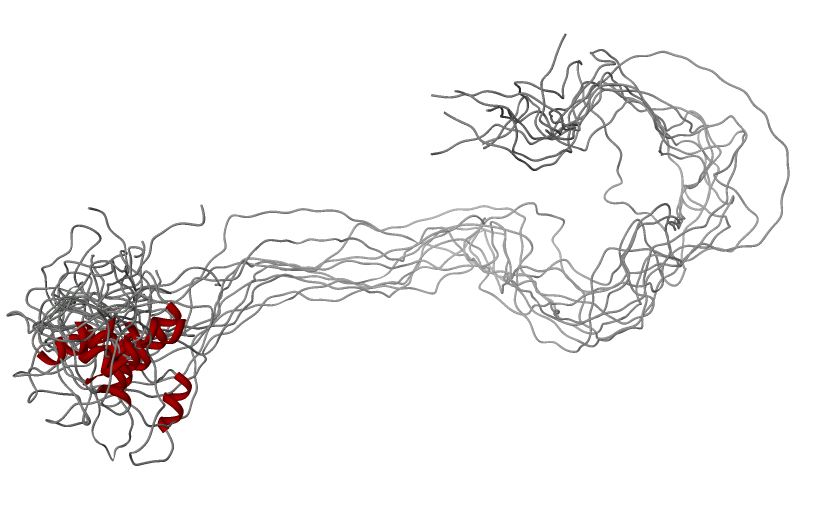
While this works for many enzymes and receptors, it is largely useless against transcription factors—proteins that act as the master switches for gene expression. Transcription factors are notorious for being "intrinsically disordered." They are, in the words of Talus Bio CTO Dr. Lindsay Pino, like a "plate of spaghetti."
"If you try to fold a transcription factor, you just get a plate of spaghetti," Pino explains. "You can’t do drug discovery on a plate of spaghetti."
Because these proteins constantly shift their shape, they lack the rigid, stable binding pockets that structural models like AlphaFold or Boltz-2 require to function. This has led to a massive, persistent gap in medicine: of the roughly 20,000 human proteins, 87% remain without an approved drug or a known potent small-molecule ligand. These targets have long been labeled "undruggable," effectively off-limits to conventional pharmaceutical research.
Chronology of an AI Breakthrough
The development of Ptarmigan-1 represents the culmination of a multi-year effort to move away from structural dependency.
- Pre-2026: The industry remains heavily focused on structural prediction, with models like Boltz-2 leading the way in predicting molecular structures and binding affinities. However, the computational cost of "co-folding"—simulating the interaction between a drug and a protein—remains prohibitively high for large-scale discovery.
- July 2026: Talus Bio releases a landmark preprint detailing the limitations of current structural models and introducing their "structure-free" methodology. The team highlights that they have successfully searched a 3.4-billion-compound library against 20,431 human proteins.
- September 2026: Benchmarking results are finalized, demonstrating that Ptarmigan-1 can perform virtual screens with unprecedented speed, effectively reducing the timeline of massive compound screening from years to mere hours.
Data-Driven Discovery: How Ptarmigan-1 Works
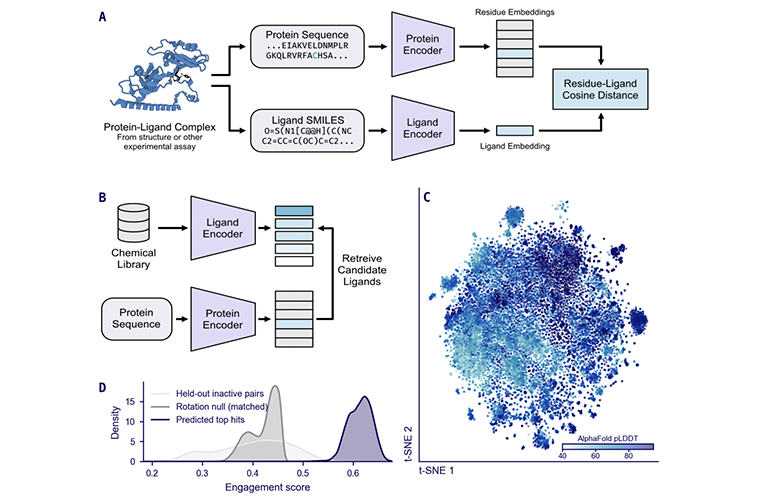
Unlike its predecessors, which rely on the 3D coordinates of amino acid chains, Ptarmigan-1 is built upon real-world mass spectrometry data. Talus Bio trains its model to recognize the "fingerprints" of target engagement—the chemical signals that occur when a compound interacts with a protein inside a living cell.
By ignoring the 3D structure, the model avoids the "spaghetti" problem. Instead of asking, "Where does this molecule fit in the pocket?", the model asks, "Does this molecule interact with this protein, based on the patterns we have observed in experimental proteomics?"
Computational Efficiency
The economic implications of this shift are as significant as the biological ones. Computational drug discovery is often limited by the sheer power required to simulate atomic interactions.
"A big experiment in drug discovery in the real world is a million compounds," explains Talus Bio CEO Alex Federation. "That would cost something like $100,000 to $1 million and take months, for one protein. Folding the protein is the computational expense."
In head-to-head testing, the contrast is stark. Running on a single Nvidia H100 GPU, Ptarmigan-1 processes compounds at a rate of 10 milliseconds each. In contrast, Boltz-2—a highly capable structural model—requires approximately 54 seconds per compound.
When applied to a million-compound library, this efficiency creates a massive competitive advantage:
- Structural models: Nearly two years of continuous computation.
- Ptarmigan-1: Under three hours.
Validating the Model: The STAT6 Retrospective
To prove that their model wasn’t just fast, but accurate, the Talus team conducted a retrospective study on STAT6, a transcription factor implicated in several inflammatory diseases and cancers.
They tested the model against a library of inhibitors found in Pfizer patents published after the cutoff date of their model’s training data. The results were striking: Ptarmigan-1 identified active binders with an Area Under the Curve (AUC) of 0.94. In the same test, Boltz-2 and traditional docking methods scored 0.58, a result effectively indistinguishable from random chance.
This suggests that for disordered proteins, structural prediction models are not just slow—they are fundamentally mismatched to the biological reality of the target.
Official Perspectives and Future Implications
The leadership at Talus Bio is careful not to frame Ptarmigan-1 as a replacement for all existing tools. Rather, they see a "structure-free" future as a necessary evolution of the current pipeline.
"We’ve been sitting on these targets we’ve known about for decades, that we know are good targets," says Dr. Pino. "We just haven’t had the tools to find them yet."
The current consensus, supported by the company’s recent preprint, is that structural models and structure-free models are complementary. Ptarmigan-1 is ideally suited for "top-of-funnel" screening, where the goal is to narrow billions of candidates down to a few thousand potential leads. Once those leads are identified, structural models can then be used to refine and optimize the compounds for better binding.
Implications for the Pharmaceutical Industry
The implications for oncology and rare disease research are profound. If transcription factors can be drugged, the pharmaceutical industry could potentially address the root causes of cancers that were previously considered death sentences.
Furthermore, the speed at which Talus Bio can screen the entire human proteome—accomplishing in a day what would have historically taken decades of supercomputing time—heralds a transition from "bespoke" drug discovery to "proteome-scale" discovery.
As the industry moves forward, the success of Ptarmigan-1 serves as a reminder that in biology, the best map isn’t always the most detailed one. Sometimes, the most effective way to solve a complex problem is to stop looking at the shape of the mess and start looking at the data it leaves behind.
With 3.4 billion compounds now searchable against the entire human proteome, the "undruggable" era may finally be coming to an end. For patients waiting for new therapies, the speed at which this technology can navigate the "spaghetti" of the human cell could be the difference between a lifetime of disease and a pathway to a cure.
About the Author